Product contentCatalog to Shopify
Public launch, 30 October 2026
Sirv AI Studio
I started Sirv Studio in December 2025. On 30 October 2026 the new Studio took over www.sirv.studio: one question to set up, 25 free fixes and a three-step path to a first publish.
- 01Catalog scan
- 02AI batch
- 03Human review
- 04Safe publish
60-second summary
The shape of the product
- Role
- Creator, product lead, architect and principal engineer
- Problem
- Keep AI-assisted product content correct from intake through publication
- What shipped
- Catalog scanning, AI batches, supplier portals, review, multi-language PIM, Shopify publishing, channel exports, rollback, API and MCP
- Real use
- Enterprise supplier workflow in production
- Team
- Igor, Veniamin, Mariia and other contributors. Max Wish contributed substantially from March to June 2026.
- Current state
- Public launch at www.sirv.studio on 30 October 2026
Contributions
Who built what
Igor Varyvoda
Creator, product lead, architect and principal engineer. Conceived Studio and built and shipped the product end to end.
Max Wish
Made substantial contributions to the design system, virtualized data grid and asset interface from March to June 2026, including reusable grid packaging, column sizing and Sid-Kit components.
Veniamin Krachun
QA, including the testing and verification infrastructure.
Mariia Osadcha
Products and PIM, the Spanish interface, Shopify fixes and accessibility from July 2026.
The new Studio is live
On 30 October 2026 the Studio described on this page replaced the old app at www.sirv.studio. Existing accounts move across with their plans and credits, and existing API keys keep working.
The launch is built around the first hour, not the tool count. Setup asks one question: where are your products now? The answer can be Shopify, a spreadsheet, a folder of photos or a sample catalog of 48 products. Then Today walks the new workspace through three steps: bring products in, fix the gaps, then publish to Shopify, export a CSV or use the photos.
- 25 free setup fixes. AI fixes on up to 25 images cost nothing until the first publish. The Free plan adds 25 credits every month.
- Billing inside the app. Credit packs, automatic top-up and plan changes with the price shown first. Shopify merchants can pay through Shopify.
- Product content in more than one language. Copy per language, images tagged by language and Shopify storefronts that show the right images in each market. The interface also speaks Spanish.
- A real PIM layer. Product families, attribute groups, variant prices and imports that create attributes as they go.
- More places to publish. Shopify sync, CSV feeds with mapped columns and an ABOUT YOU export. Amazon and eBay are in preview.
- One Review area. Supplier submissions, AI results, design work and activity sit in one queue before anything goes live.
- Search that understands photos. Search by image, typo tolerance, Spanish word forms and search by meaning on Growth plans.
Between the July snapshot and launch day the repository grew from 11,950 to 24,323 commits. October alone had 6,433.
Start free at www.sirv.studio (opens in a new tab)
It started over a beer
Some coworkers were visiting me in Herceg Novi. Over a beer, we started talking about what current AI models could build. I said I would build the first version in a day.
The next morning I started at six. Initial commit from Create Next App landed at 6:35 on 2 December 2025. Background replacement worked by 8:00, virtual try-on by 8:23, and multi-angle product shots by 8:45. Auth, billing, rate limits and Sirv storage landed before the 12:05 MVP merge. The afternoon added batch processing and side-by-side comparison. The repository records 31 commits that day.
- Create Next Appthe empty repo becomes a product bet
- first AI toolbackground replacement and model selection
- virtual try-onsecond tool family is already live
- product-shot toolsangles, lighting removal, more image work
- MVP mergeauth, billing, rate limits, Sirv storage
- cleanup passbatch mode and compare mode were already in
Six days later, the workflow canvas existed. Durable Inngest jobs followed after twelve days, an MCP server after eighteen and the embedded Shopify app after twenty-five. December closed at 602 commits. The main product areas were already visible.
I took Studio from that first commit to the production platform described here. Max Wish made major contributions to the design system, virtualized data grid and asset interface from March to June 2026. Veniamin Krachun built QA and verification infrastructure. Mariia Osadcha joined in July and took on products, the PIM and the Spanish interface. The separate build record has 48 dated milestones and the commands behind its repository counts.
- A product before lunchImage tools, auth, billing, rate limits, Sirv storage, batch mode and compare mode all land on day one.
- Durable jobs and the first MCP serverLong runs move to Inngest and stream progress. Agents get a dedicated tool surface.
- Five entry surfaces in four daysShopify, Zapier, n8n, MCP OAuth and the OpenAI Apps SDK can start the same work.
- The asset library lands in a dayAssets, tags, filters, R2 storage, product links and operation history form the DAM.
- Multi-org, roles and share linksNested collections, role-based access and subfolder share navigation turn the library into a team product.
- The first supplier portalScoped upload links, an approval queue and before-and-after autofix review turn intake into a defined process.
- SFTP, SAP, catalog import, live Shopify syncSupplier delivery and product edits flow in through retry-safe GraphQL handling.
- A real supplier spec, proven end to endThe Alkosto pipeline drives reusable validation, product assignment, autofix, review and delivery.
- Imports and side-effects go durableCancellable background jobs and an event outbox, so a retry can't casually duplicate work.
- Next.js replaced in 72 hours, liveThe billing, multi-tenant application moves route by route to TanStack Start while users remain on it.
- Workflows gain real triggersUploads, schedules, product changes and authenticated webhooks start runs, with dry-runs and attempt history.
- One product-content data pathA documented path from org to source, product, variant, assignment, asset, publish projection and readiness.
- Workflows learn DAM and PIM operationsThe orchestrator reads from and writes into the content system through a typed Effect-based operation kernel.
- Risk-tiered quality gatesEdit, session and release gates are joined by an analytics dashboard and a coverage matrix checked by tooling.
- The catalog-health loop becomes executableA detected product gap connects to a controlled action: AI fix, supplier request, Shopify sync or channel export.
- The product points at activationCatalog health leads the dashboard. Workflow recipes and drift-aware publishing run on selected products.
- The interface learns SpanishSpanish (Colombia) becomes the first translated locale.
- Off Vercel, onto our own serversThe app moves to a Hetzner node with its own deployer. A second node and a load balancer follow a month later.
- Billing moves inside the appCredit packs, automatic top-up, plan changes with the price shown first and Shopify Billing.
- One question to set up, and a new databaseSetup asks where the products live. The same day, production Postgres moves to PlanetScale.
- A PIM with families, groups and languagesProduct families, attribute groups, variant prices and per-language images reach Shopify storefronts.
- Public launch at www.sirv.studioThe new Studio replaces the old app. Accounts, plans and credits move across.
What it does
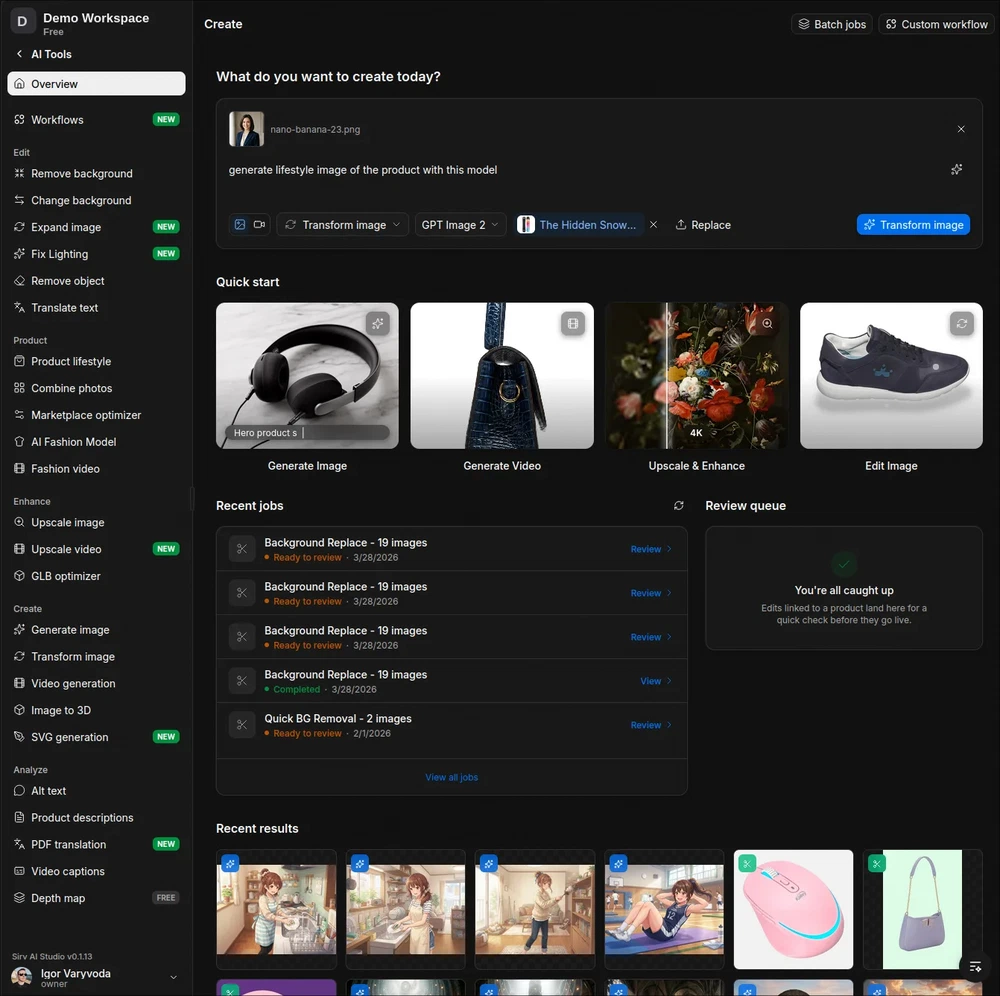
The product is organized around one loop: ingest → fix → validate → review → publish → track.
- 30+ AI tools for background work, upscaling, lifestyle images, ghost mannequin, virtual try-on, alt text, descriptions, translation, 3D and video. The registry holds 73 model IDs, routed mainly through fal.ai, OpenAI and OpenRouter. Colour Variants is the newest tool: it recolours a photo or a 360 spin into up to 12 colours, with a free preview.
- A visual workflow orchestrator: a drag-and-drop DAG builder with 40 registered step types, so a merchant can chain “remove background → generate lifestyle shot → write alt text → human review → push to Shopify” and run it across an entire catalog. Workflows execute on durable background jobs with pause/resume, review gates and live progress, and can be triggered from the UI, the API, webhooks or an AI agent.
- A supplier portal gives brands a scoped upload link or SFTP drop. Files are checked against filename, SKU and image rules, sent through AI autofix and held for review before they can reach the catalog.
- Marketplace checks validate dimensions, backgrounds, watermarks and frame fill against Amazon, eBay, Walmart and Shopify rules. Autofix can repair some failures.
- Asset and product management adds search by image, duplicate detection, auto-tagging and licence tracking that can block a publish. Products carry families, attribute groups, variant prices and content in more than one language.
- Channels and integrations cover Shopify sync, CSV feeds, an ABOUT YOU export, Amazon and eBay in preview, Zapier, n8n, a REST API and MCP.

The products view: every product scored for content readiness against its channel’s requirements.
How it’s built
The app is a TanStack Start + React 19 application (migrated off Next.js, running the React Compiler) built with Vite. On 25 September it left Vercel. It now runs as a Nitro build on Bun across two Hetzner app nodes behind a load balancer, with rolling blue/green releases and Cloudflare in front. A deployer watches main, and a new commit is live in about five minutes. October had 111 promotions from dev to main.
Data lives in PostgreSQL behind Drizzle ORM, on PlanetScale since 22 October, with 460 committed migrations. The old Hetzner cluster stays as a frozen rollback copy. Background work runs on 179 Inngest functions across sync, publishing, billing, imports, repair jobs and workflow execution, self-hosted on Hetzner. Redis with Sentinel handles rate limiting, Sentry/PostHog/Grafana handle observability and the repo contains 7,980 test and spec files across unit, integration, contract, Storybook and browser layers. Capacitor shells package it for iOS and Android.
Max Wish helped build the internal design system and custom virtualized data grid behind the asset and product tables. His commits include extracting a reusable grid package, fixing column auto-fit sizing and refining Sid-Kit components. Development continued after his June contributions: September commits from me and other contributors cover scroll performance, accessibility and dependency updates. Veniamin Krachun built the E2E and QA systems used to verify releases.

The assets table uses the shared virtualized data grid for live thumbnails, sortable metadata and large result sets. Max Wish made substantial contributions to its development.
Three problems were harder than the rest.
Publishing to someone else’s store, safely
Studio writes to live Shopify catalogs. A publish must not overwrite a newer merchant edit.
Before writing, Studio compares the last sync with changes in Shopify and Studio. Each product is classified as in_sync, shopify_newer or studio_newer. If Shopify is newer, Studio surfaces the conflict instead of overwriting it. Reconciliation also catches a source image that was deleted or replaced after the last sync.
Writes themselves are versioned and idempotent: publishes go through explicit strategies (add alongside the original, replace, set featured, alt-text-only), every published asset keeps its version history with rollback, and an event outbox guarantees that a retried job can’t double-publish. “Publish safely, roll back instantly” is the promise the whole layer is built to keep.
Supplier uploads without the chaos
Supplier files often arrive by email or shared drive with wrong names, dimensions or missing SKUs. Somebody then has to prepare them for the store.
Each supplier gets a scoped upload portal, chunked batch upload or SFTP drop. Studio checks filename patterns, SKU matches, gallery slots and image rules. AI autofix repairs supported failures. A reviewer sees the product, shot list and failed checks before accepting or rejecting the submission. Database guards stop supplier content from skipping review on its way to a live store.
This supplier workflow is in production with an enterprise customer.

The review queue holds supplier files before publication. Automated checks flag problems, autofix repairs supported failures and a reviewer approves the result.
Making it operable by AI agents
Studio ships a production MCP server with stdio and hosted HTTP transports. It exposes 55 tools for AI processing, asset management, product changes, Shopify sync, supplier review and Sirv CDN files. It works as a custom connector in Claude and in ChatGPT developer mode. A published OpenAPI surface contains 70 operations.
Agents receive the same permissions, approvals, budgets and rollback rules as the UI. Authentication uses OAuth 2.0 with PKCE or API keys. Mutating and credit-spending tools check authorisation on the server. Every call validates organisation membership, and MCP annotations identify read-only, destructive and idempotent operations. An agent can run a batch or workflow, but it cannot skip a required review.
What the code had to survive
The repository count is large, but commits alone say little about quality. The stronger evidence is in the failure cases. More than 900 written plans now record why a change matters, how it should work and how it will be checked. The earlier record lives in the git log and changelog. These are examples from both.
Money, where the tolerance is zero.
- A two-phase charge that deducted nothing. Tool jobs bill in two steps: reserve, then top up once the real cost is known. Both used an idempotency key derived from the job ID, so the credit layer treated the top-up as a replay and debited zero. The wallet and ledger agreed on the wrong number.
- A ledger that could not rebuild a balance. The credit
transactionstable allowed the same type to be positive, negative or zero.REFUNDalso mapped to both signs. A disputed balance could not be reconstructed. A signed journal now enforces the direction of every entry and will run beside the old system for a full billing cycle before cutover. - A free extra month on every upgrade. A mid-cycle proration invoice fell through to the renewal path and granted a full month of credits. Full refills now run only on true renewals.
Writing into a store you don’t own.
- Day 25, before there were users to lose. The embedded Shopify app shipped its security with the MVP: HMAC-verified OAuth callbacks, an AES-256-GCM-encrypted state cookie and mandatory session-token verification on the
x-shopify-shopheader, so nobody can pass someone else’s store and act on it. (fix: Shopify integration security hardening, Dec 27, 2025.) - Out-of-order webhooks restored deleted products. Per-event idempotency handles a repeated event, but it does not order two different events. An older
products/updatearriving afterproducts/deletere-created assets. Per-product keys, staleness checks and a delete tombstone fixed it. - A batch push reported failure as success. A partial failure still fired the success path and removed the failed items from view. A retry then duplicated catalog images because Shopify’s media API has no idempotency key. Every item now finishes as pushed, retryable failure, pushed with warning or indeterminate and unsafe to retry.
The failures that raise no error.
- A dead letter reported success. An outbox event exhausted ten retries, returned success to the queue and alerted nobody. A customer endpoint that stayed down for a day lost every delivery. The missing error was the bug.
- The 1,000-step limit. Inngest caps a run at 1,000 durable steps. One step per item worked in development, then failed on large production jobs. The fan-out now uses two steps per 100-item chunk. A 42,000-item job takes 840 steps.
- Unconfirmed uploads escaped quota. A direct R2 upload that was never confirmed left an untracked object billed to the organisation. A bucket expiry rule would also have deleted live assets sharing the prefix, so the cleanup uses application-level bookkeeping.
Tenant isolation and agent permissions.
- A cross-tenant store hijack appeared across two changes. One change reused an account after an email collision. Another left a synthetic store address available through public signup. Together, they let an attacker bind a merchant’s store to the wrong organisation. Review of the combined changes caught it.
- A bulk delete checked ownership too late. The R2 delete used client-posted asset IDs before the organisation-scoped database delete ran. A user in one organisation could delete another organisation’s version history.
- An
idempotentHintmisled agents. Several credit-charging tools claimed retries were safe. A transport timeout could therefore charge again and create duplicate outputs across batches of up to 100 images. - A dangerous account-linking default.
allowDangerousEmailAccountLinkingmerged an OAuth login into an existing account with the same email. It was disabled in the first security pass, together with an IDOR fix that scoped payment queries byuser_id.
Checks that caught bad code.
- Isolation tests that proved nothing. The tests asserting cross-tenant isolation stubbed
db.execute, so the orgWHEREclauses that actually enforce it had never once run in CI. Rewritten to execute the real SQL against two seeded orgs, including the case where org A asks for org B’s asset and must get nothing back. - The money gate had no real coverage. The out-of-credits check used a hardcoded funded user, so the branch that blocks a paid run never executed in the test.
- A type guard never ran. A
satisfies AppSessionannotation sat outside the typechecked project. Storybook had been rendering a connected user as disconnected without failing CI.
This is normal production work for software that touches money, stores and customer data. The git log measures output. These incidents show some of the correctness work behind it.
Replacing the framework in production
By spring, Studio had outgrown Next.js. I moved the production application to TanStack Start while users remained on it.
The supplier portal shipped on 2 April. The first TanStack Start slice landed on 8 April. On 9 April, a compatibility shim kept old imports working while routes moved one by one. The final Next.js runtime dependencies were removed on 10 April. The migration took about 72 hours without freezing other work.
The migration depended on broad tests, route-by-route checks and review gates. Fast edits would not have been enough without them.
How a small team and a fleet ship this fast
February was the quietest month. It focused on billing, supplier intake, permissions and other production work, and still contained 316 of my commits. In the first 333 calendar days, eight had no commit of mine.
On launch day the repository holds 24,323 commits: 15,083 mine, 5,940 from Veniamin, 727 from Max, 714 from Mariia and 1,859 from other contributors, bots and alternate identities. Commit volume is not value. The relevant observation is that output increased after the agent workflow became more structured.
- VibeQ holds human and agent tasks. Agents claim work through MCP, check for duplicates and update the task as they work.
- The Clanker Army turns reviewed plans into isolated worktrees and runs them in supervised batches.
- Agent roles such as QA lead, security lead and performance reviewer have written instructions in the repository.
- Sirvant accepts a Slack request and can dispatch a disposable worker to investigate or implement it.

VibeQ shows active work, stalled reviews, bug priority, product hotspots and the coverage gate used before release.
My work in that loop is to set scope, approve plans, use the product, review evidence and decide what ships. Behaviour changes need tests, and every release passes a blocking quality gate.
One person owns the development branch each day and pushes to it directly. A short morning sync and handoff replace an internal pull-request queue. This works because branch ownership is explicit and the automated checks are blocking.
I wrote the broader argument behind this operating model in The programmer who stopped typing. This page keeps the claim grounded in the Studio evidence.
When Veniamin joined QA, his weekly output was near twenty commits while he built the coverage matrix, anti-forgery checks and agent workflows. Two months later, the weekly counts were 277, 309 and 188. The increase followed the QA system, not a change in typing speed.
The correction
Most numbers on this page measure what was built. The supplier portal running with an enterprise customer is the clearest evidence of real demand.
The repo’s own July assessment is blunt: we have shipped more than we have proved.
Fast implementation created more features than the team had proved it needed. Every feature adds documentation, support, billing cases, browser checks and migration work. Agents can produce code, but they do not create demand or decide what should be removed.
Q3 therefore froze new tools, channels and workflow steps unless approved explicitly. Work moved to activation, onboarding, rollback proof and helping merchants reach a first approved publish.
The freeze mostly held. Workflow step types stayed at 40 from July to launch. What shipped instead was the road to a first publish: one-question setup, a sample catalog, free setup fixes, Today and billing that works without leaving the app. October did add channel exports and a colour tool.
Building quickly is no longer the main problem. Choosing what to build is. The launch is where the July verdict gets tested against real merchants.
So is it any good?
I also ran a structured self-audit. Ten reviewer agents, one per domain, inspected the code, schema, migrations, tests and CI configuration. The repository then contained roughly 512,000 lines of handwritten TypeScript, 7,800 files, 162 database tables and 4,751 test and spec files. Claude Fable combined the reports and rechecked the largest findings at file level. The scoring guide treated 5 as typical startup quality, 7 as solid production quality and 9 or above as exceptional.
The verdict: 8.25 out of 10.
These were ten passes from one model family, not ten independent opinions. The result is a self-audit, not an external benchmark. Larger findings were checked again against the files before scoring.
The strongest areas use executable checks. Import-safety tests protect architecture boundaries. The E2E coverage matrix requires a signed result from a real run. Static analysis checks organisation scoping, and the schema prevents cross-tenant links.
The audit also identified unfinished variant editing, limited channel sync beyond Shopify, storage quotas still in warning mode, several 2,000-line components, and circular imports in the library layer. Each confirmed finding received an implementation plan. By launch, asset, storage and product quotas block at the limit, and variants have their own prices. Shopify is still the only direct channel sync. The other channels are file exports.
Rechecking reduced several findings. One suspected legacy billing path had no production callers. The reviewers also estimated that comparable scope would require more than 200 engineer-months in a conventional team. That estimate is directional, but it gives context for the roughly ten months spent here.
Studio also has exponential-backoff retries with jitter, per-operation circuit breakers on AI providers, content-based idempotency keys, Redis-backed rate limits and restore-drilled database backups. They have no screenshots, but the product depends on them.
Try Sirv AI Studio (opens in a new tab) · Check the build record →
What users changed
A real supplier workflow turned the portal from a simple upload link into intake, review and publishing.
What remains imperfect
I have shipped more than I have proved. The launch is the test: activation, first publishes and rollback evidence matter more now than another tool.